CREATEVISION AI · WORKFLOW TESTS
What does a complete product edit chain cost?
Tested 6–7 November 2026 · three repeats per tested configuration.
Seedream’s three-edit chain is quoted at 150 credits; Flare and Sunburst Medium are each 495.
Flare’s median observed chain wait was 49.8 seconds, Sunburst’s 91.8 and Seedream’s 204.1 in this batch.
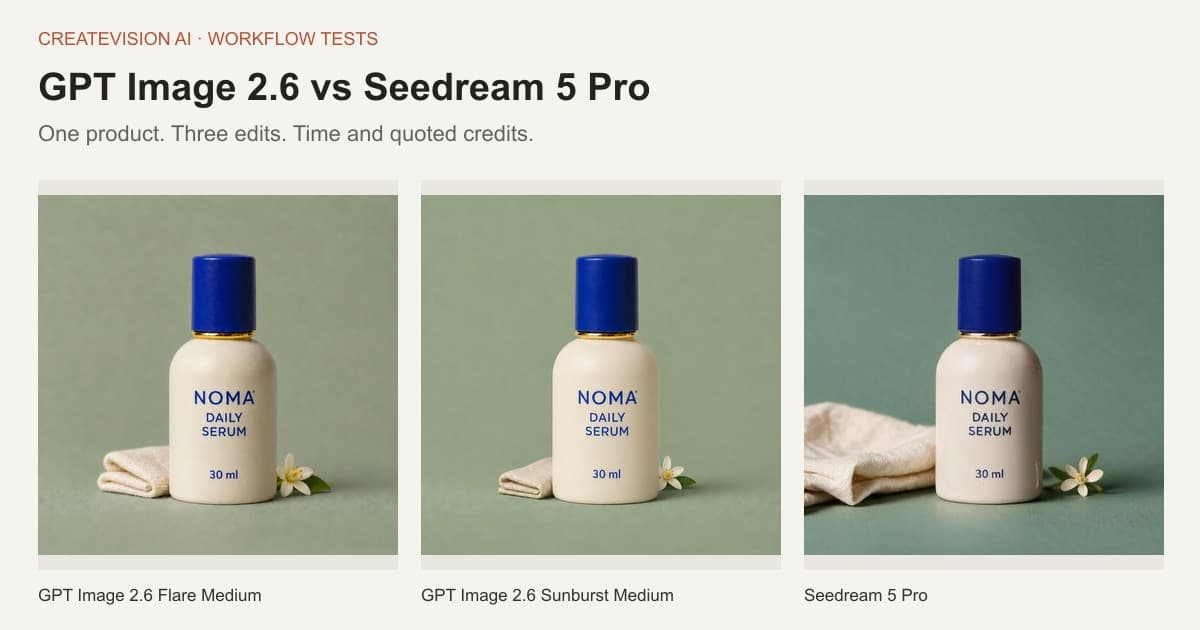
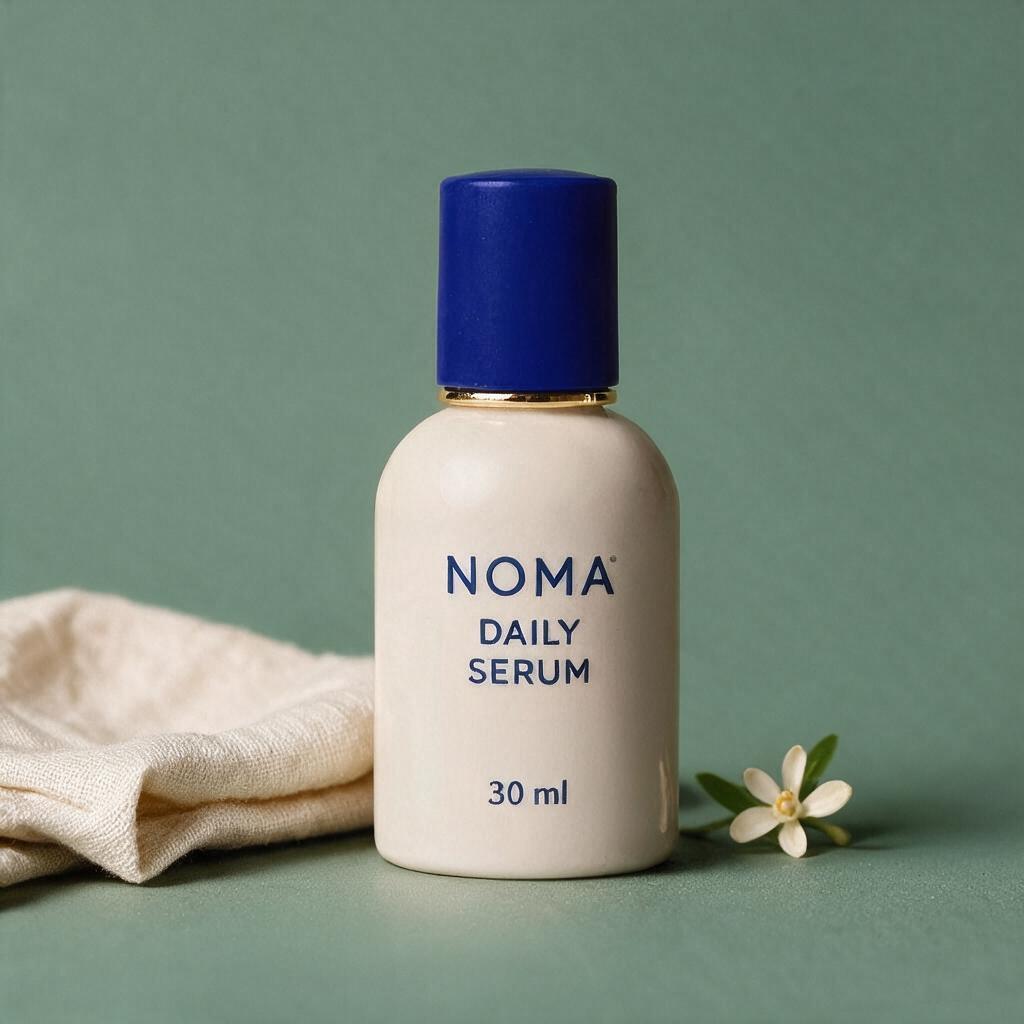
All nine final product images retain readable core label text. Seedream repeat three adds an orange-colored flower rather than the requested small orange blossom.
Treat the label as a delivery requirement.
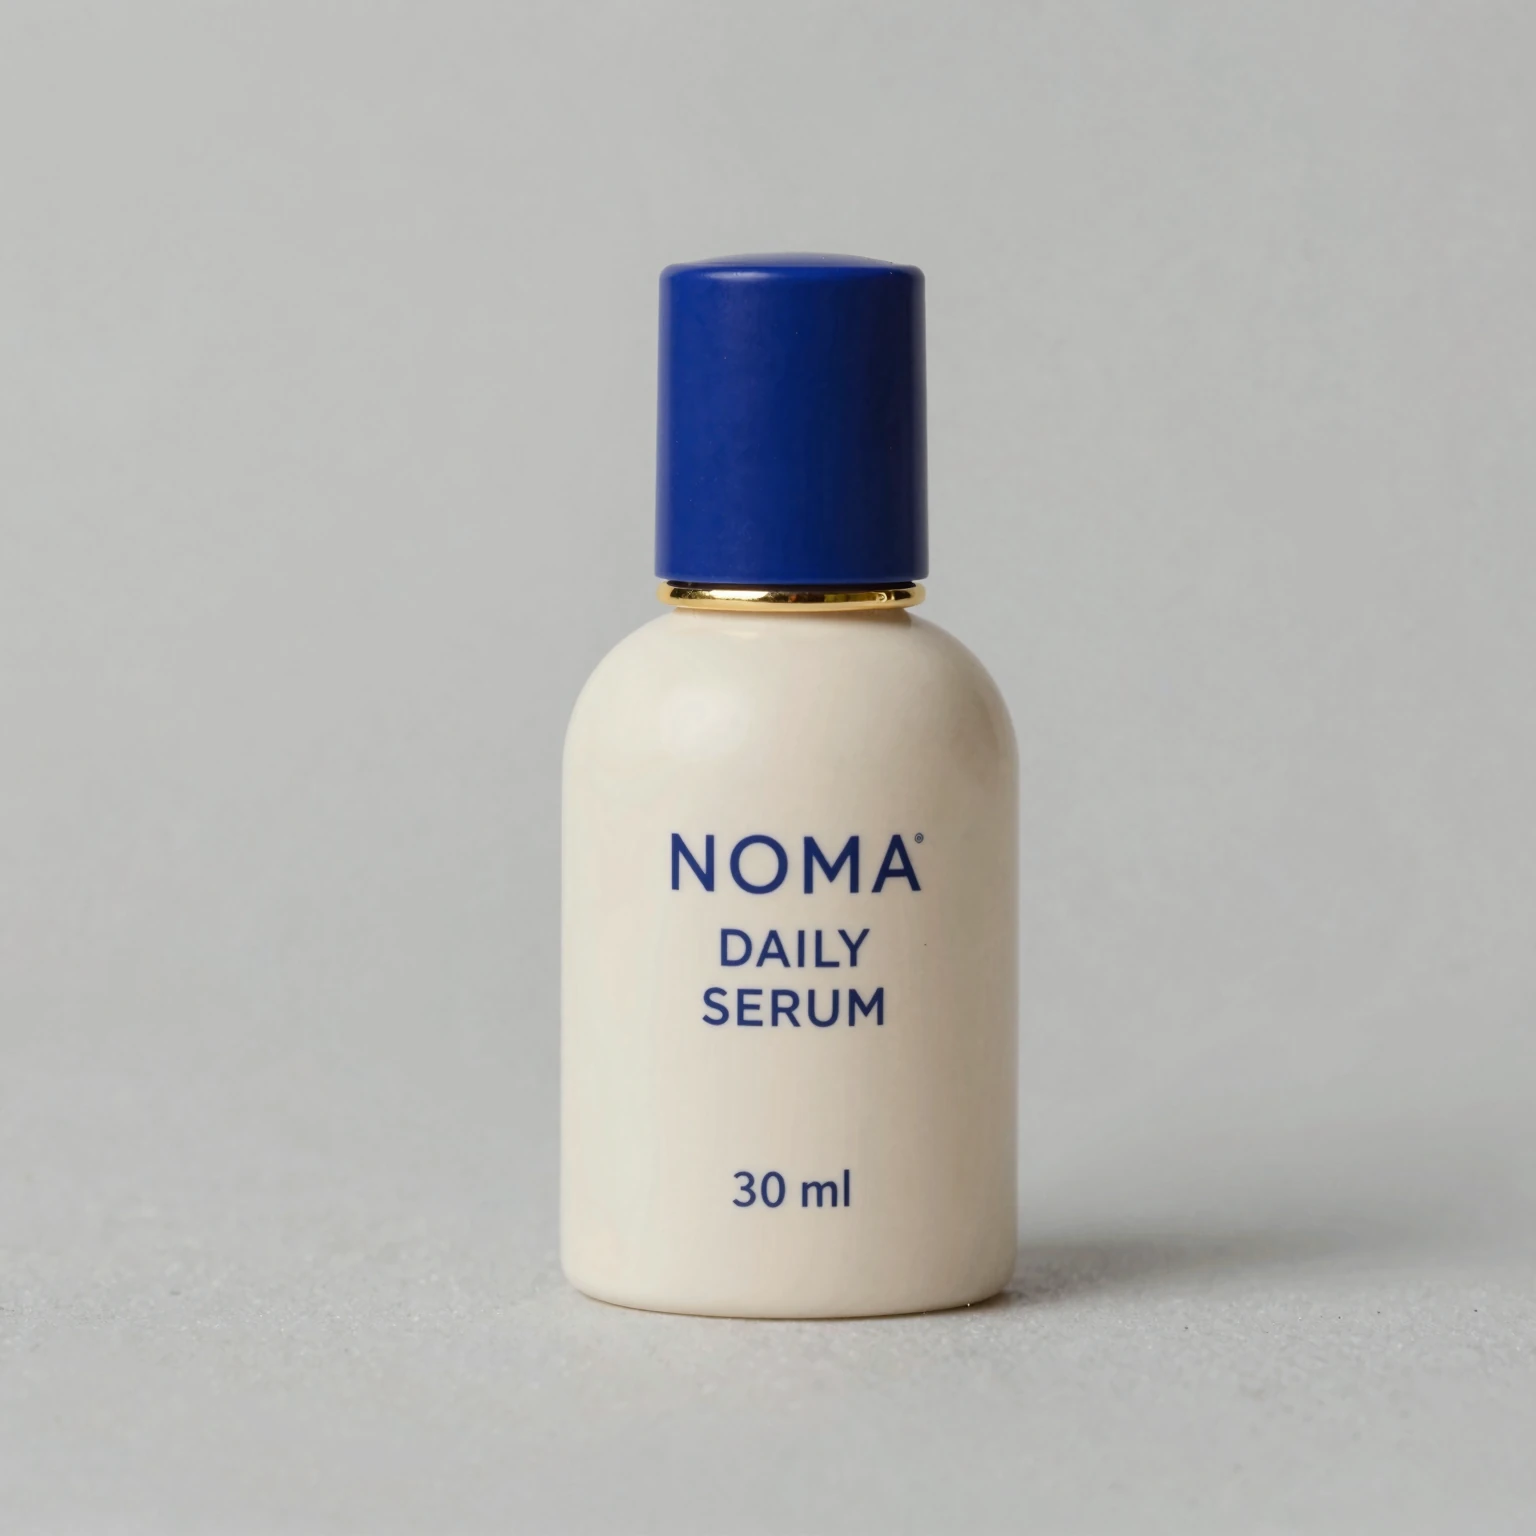
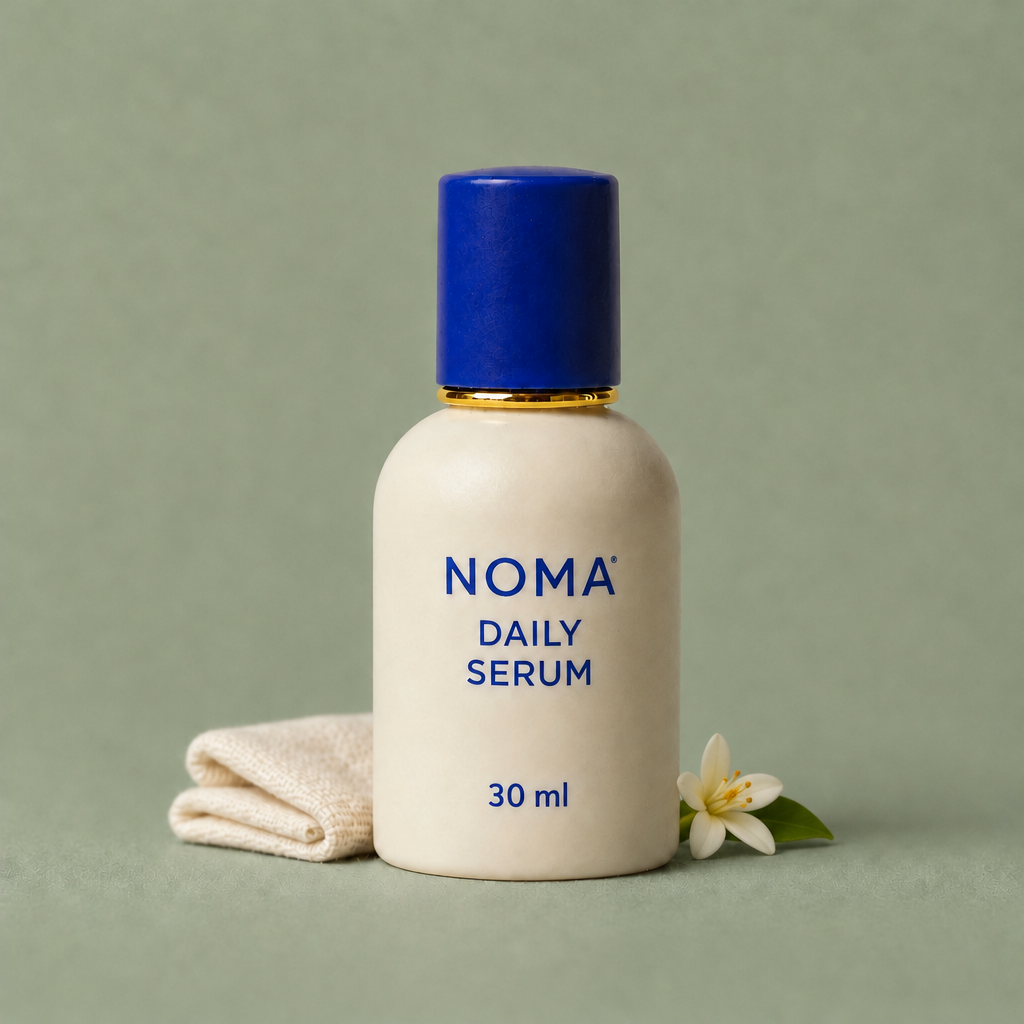
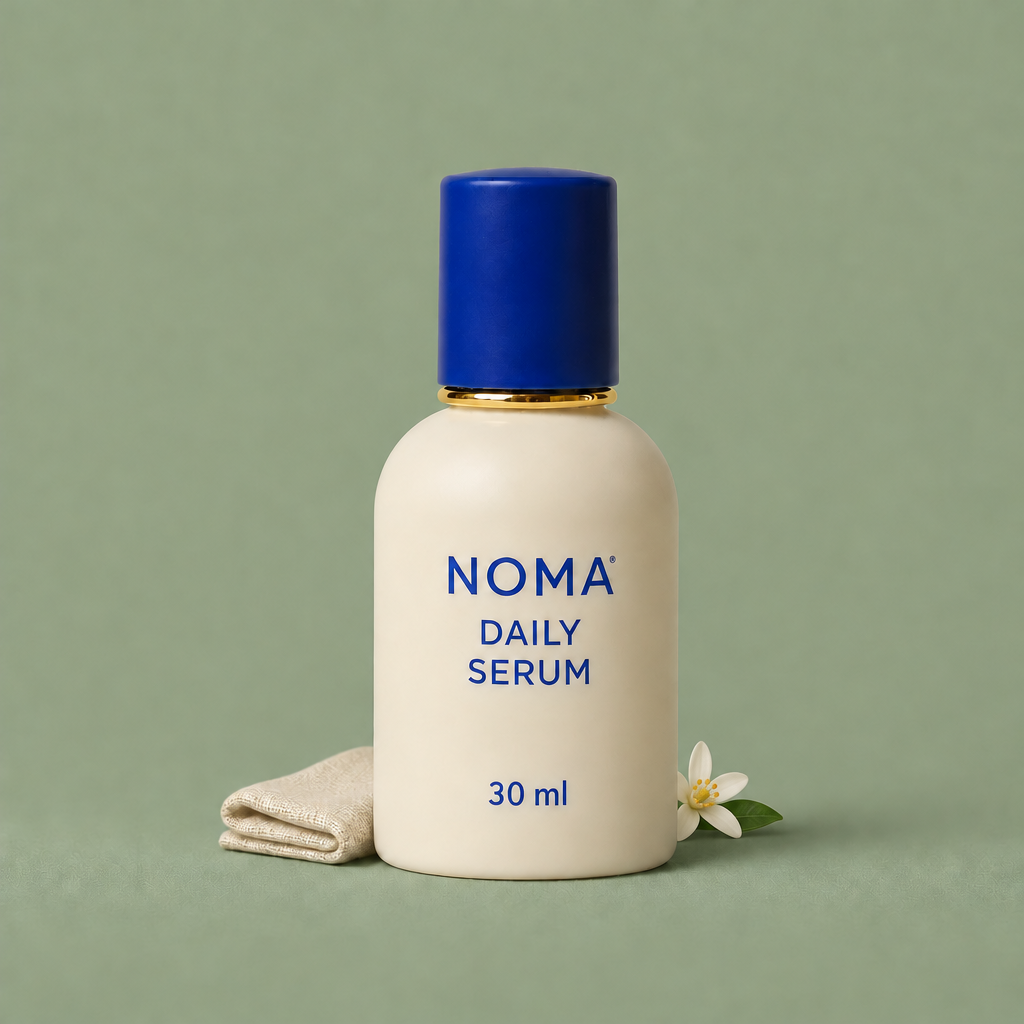
Glossy lighting can make a broken product look convincing. Before judging mood or texture, check NOMA, DAILY SERUM and 30 ml at full size. Then inspect the cap, brass collar, silhouette and the linen introduced in the previous round. A campaign image needs both a useful scene and the right product.
- For this simple product scene, we would start with Seedream when conserving credits matters and the longer observed wait is acceptable. Its 150-credit chain preserves the bottle and required label in these examples; a higher quote is not automatically necessary for a usable scene.
- Flare is our first alternative when turnaround matters: its three chain waits ranged from 45.9 to 101.7 seconds, compared with 203.8 to 225.1 for Seedream. This measures the whole submitted workflow, including queues and reference transfer, not intrinsic rendering speed.
- The useful failure is small enough to overlook: Seedream repeat three interprets orange blossom as a bright orange flower. Other repeats produce pale blossoms. Check the prop as well as the label, and describe color and species explicitly when botanical accuracy matters. We did not retest a rewritten prompt.
Compare the outputs
Same brief, visible differences.
Product
Starting reference
GPT Image 2.6 Flare Medium
1:1 · 1K · medium
Prompt, settings and references
Add only one small orange blossom at bottom right behind the bottle. Preserve the exact bottle shape, ivory body, cobalt cap, brass collar, cream linen cloth, sage background, camera, scale and text NOMA / DAILY SERUM / 30 ml. No other changes.
References: 1 · high
Starting reference ↗GPT Image 2.6 Sunburst Medium
1:1 · 1K · medium
Prompt, settings and references
Add only one small orange blossom at bottom right behind the bottle. Preserve the exact bottle shape, ivory body, cobalt cap, brass collar, cream linen cloth, sage background, camera, scale and text NOMA / DAILY SERUM / 30 ml. No other changes.
References: 1 · high
Starting reference ↗Seedream 5 Pro
1:1 · 1K · 1K
Prompt, settings and references
Add only one small orange blossom at bottom right behind the bottle. Preserve the exact bottle shape, ivory body, cobalt cap, brass collar, cream linen cloth, sage background, camera, scale and text NOMA / DAILY SERUM / 30 ml. No other changes.
References: 1 · —
Starting reference ↗The first repeat opens by default. Switch repeats to inspect variation; all returned images remain available. A failed task is retained in the public record and is not counted as a successful image. Loads the tested prompt, references and parameters into the generator. Review the current quote and press Generate yourself.
Waiting once is not finishing the job.
Read the complete chain alongside its quoted cost. A fast image that breaks the label may need a correction; an expensive image may still miss the brief. We have not priced hypothetical retries or human retouching.
| Tested setup | Requests | Observed wait · Median | Range | Credits per three requests |
|---|---|---|---|---|
| GPT Image 2.6 Flare MediumProduct | 9 | 49.8 s | 45.9–101.7 s | 495 |
| GPT Image 2.6 Sunburst MediumProduct | 9 | 91.8 s | 82.8–141.1 s | 495 |
| Seedream 5 ProProduct | 9 | 204.1 s | 203.8–225.1 s | 150 |
A chain total covers three requested edits, excluding the shared starting image.
Observed waits include submission, reference transfer, queue, network and two-second polling. Up to three requests were in flight. They describe this batch, not guaranteed model speed.
These are CreateVision AI credit quotes for the tested settings, not API prices or a universal price per image. Check the current quote before generating.
How we tested
We fixed the briefs before generating and retained every first request. Each subject starts from the same image made with Z Image Turbo, a model outside the comparison. Each editing step uses that model’s previous result. We ran three independent chains per subject and model. Requested 1K tiers can return different pixel dimensions; inspect the dimensions in the public record. No output was retouched or rerolled for quality.
Visual assessments use a fixed checklist: requested change completed, protected details preserved, required words correct, no unwanted additions. They are editorial judgments, not biometric identity scores.
The identical brief is a reproducible baseline, not the best prompt possible for every model. We did not run a separate model-optimized prompt arm or a budget-matched quality sweep. Our conclusions apply to these settings and tasks.
CreateVision AI sells access to the compared models. This is an in-house editorial test, not an independent laboratory ranking. We publish the originals and our criteria so you can disagree with the assessment.
A small set of fictional subjects cannot establish reliability for every face, product, language or campaign.
Official capabilities and tested availability
An untested feature does not count as a win. GIF, SVG, markup and web search are outside the shared image-task comparison. Official GPT Image documentation and the live model pages are linked below.
Questions before you choose
Is the lowest-credit chain automatically the best value?
Only if its outputs meet your needs. We publish chain quotes, elapsed waits and visible corrections separately. We did not simulate extra paid retries to force every chain to pass.
Are these identical resolution comparisons?
The requested tier is 1K, but models can return different dimensions. The original files and exact dimensions are in the test record. This is a workflow comparison, not a pixel-matched rendering benchmark.
Can I reuse the setup for my store?
Yes. Replace the fictional NOMA reference with your product photograph and name the features that must remain unchanged. Check the current quote; the recorded quote is a dated snapshot.
Try the task with your own image.
Choose an output above to load its exact setup. Replace the fictional reference with your own and check the quote before creating.